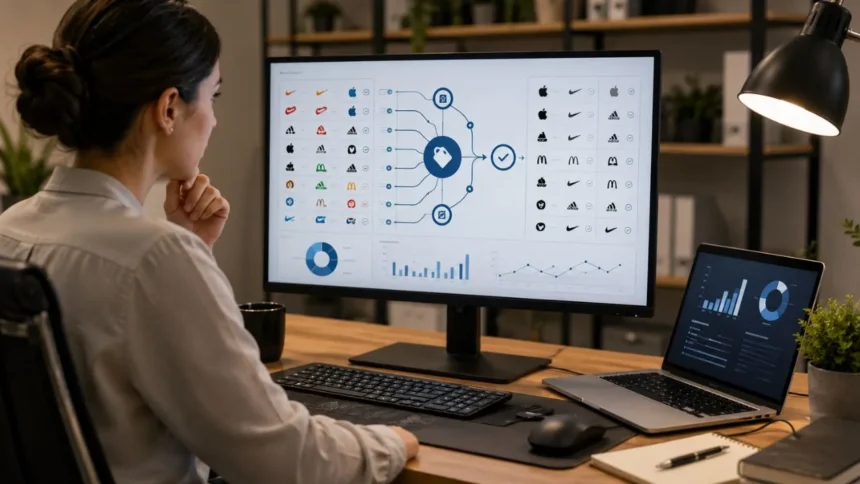
Brand names appear in many forms across websites, CRMs, product feeds, marketplaces, analytics platforms, and internal databases. A single company might appear as “Acme,” “ACME Inc.,” “Acme, Inc,” or “acme.com,” even though every variation refers to the same brand. Brand name normalization rules create consistency by transforming these variations into a reliable standard without damaging the brand’s official identity.
Normalization becomes especially important when businesses manage thousands of products, vendors, customers, or company records. Inconsistent naming can create duplicate entries, inaccurate reports, failed integrations, poor search results, and confusing customer experiences. A clear brand data standard gives teams one dependable way to store, match, display, and analyze brand names across multiple systems.
However, normalization should never mean blindly changing every brand to lowercase or removing punctuation. Some brands intentionally use unusual capitalization, numbers, symbols, or spacing as part of their identity. A strong normalization framework separates the official display name from the technical comparison value. This complete guide explains how to create brand name normalization rules that remain accurate, scalable, and practical.
What Is Brand Name Normalization?
Brand name normalization is the process of converting different representations of the same brand into a consistent format. For example, “Bright Star LLC,” “BrightStar,” and “brightstar.com” may need to map to one canonical brand depending on your data model. The goal is to reduce unnecessary variation while preserving the correct identity of each business.
Normalization is commonly used in master data management, product information systems, customer databases, merchant feeds, search engines, and analytics platforms. It helps software determine when two records represent the same entity even when their spelling or formatting differs. Without normalization, simple differences involving spaces, punctuation, or legal suffixes can accidentally create separate brand records.
A normalized brand name is not always the name customers should see. Many systems maintain both a canonical display name and a normalized matching key. For example, the official display value might remain “AT&T,” while the internal comparison key could become “att.” Separating presentation from matching prevents technical standardization from damaging official brand styling.
Why Brand Name Consistency Matters
Inconsistent brand names can quickly create duplicate records in databases and reporting systems. A sales platform might store “ABC Technologies,” while accounting software stores “ABC Technologies LLC” and a marketing tool stores “abc technologies.” When these records are analyzed separately, revenue, customer activity, and campaign performance can become fragmented across multiple versions of the same company.
Consistent naming also improves integrations between systems. Product information may move between an ERP, PIM, e-commerce platform, marketplace, advertising feed, and analytics tool. If each system interprets brand names differently, matching can fail or require manual correction. Brand normalization creates a stable data layer that makes automated workflows more dependable.
Customers can notice inconsistency as well. Seeing several spellings of the same brand across product pages, filters, search results, and invoices can make a website feel poorly maintained. Standardized brand data supports cleaner navigation and more trustworthy presentation. It also reduces the amount of manual work required when employees update catalog information or resolve duplicate records.
Create a Canonical Brand Name First
Every normalization system should begin with a canonical brand name. This is the preferred version used as the authoritative reference across your organization. The canonical value should normally follow the brand’s established public identity rather than an automatically generated format. For example, “eBay” should remain “eBay” instead of becoming “Ebay” simply because title case is your default.
Store the canonical name separately from alternate spellings or aliases. A company might have historical names, legal names, shortened names, domains, or marketplace-specific variations that still need to match the same entity. These variations can be stored as aliases while the canonical record remains unchanged. This approach makes entity resolution more accurate without sacrificing data cleanliness.
Assigning a unique internal brand ID can make the model even stronger. Names can change, but a stable identifier allows connected products, transactions, and reports to remain linked to the same underlying brand. Instead of relying entirely on text matching, systems can use the identifier as the permanent reference. Brand names then become editable attributes rather than fragile primary keys.
Set Clear Capitalization Rules
Capitalization is one of the first areas where normalization projects create unnecessary mistakes. Converting everything to title case may appear clean, but it can damage brands with intentional styling. Names such as “eBay,” “iRobot,” or “YouTube” should retain their established capitalization when shown to users. Official styling should normally take priority over generic capitalization rules.
For technical matching, capitalization can often be ignored. A comparison system may treat “ACME,” “Acme,” and “acme” as equivalent while still storing “Acme” as the preferred display version. Case-insensitive matching helps remove duplicates created by manual entry without changing the public-facing name. This distinction between display formatting and comparison logic is essential.
Create exceptions for brands that intentionally use unusual capitalization. Rather than building increasingly complicated automatic title-case logic, maintain a canonical table containing approved display names. New records can be compared using lowercase matching keys and then mapped back to the correct presentation. This provides both technical consistency and accurate brand representation across customer-facing systems.
Normalize Punctuation Carefully
Punctuation can create major matching problems because the same brand may be entered with periods, commas, apostrophes, ampersands, or hyphens. A normalization key might remove selected punctuation so “A.B.C.” can match “ABC.” However, punctuation should not automatically disappear from the displayed brand name. Some symbols form a meaningful part of a brand’s identity.
Ampersands require particular care because “&” and “and” may appear interchangeably in user-entered data. A matching layer can optionally standardize both forms when appropriate, but automatic replacement should be tested for false matches. The official display value should still follow the brand’s preferred representation. For example, a brand using an ampersand publicly should not be rewritten solely for technical convenience.
Apostrophes and hyphens can also be meaningful. Removing them from comparison keys may improve matching, while removing them from canonical display names can create incorrect spellings. Define separate rules for normalization and presentation instead of applying one transformation everywhere. This approach allows your database to recognize variations while preserving accurate customer-facing brand names.
Decide How to Handle Legal Suffixes
Legal suffixes such as LLC, Ltd., Inc., GmbH, PLC, and Corporation often create duplicate brand records. A customer-facing brand may simply use “Northstar,” while invoices or supplier files contain “Northstar Holdings LLC.” Depending on your use case, removing legal suffixes from a matching key can make it easier to identify records that belong to the same business.
However, legal entity names and commercial brand names are not always interchangeable. A corporation may own several distinct brands, while one brand can operate through different legal entities in multiple countries. Removing suffixes blindly can therefore merge businesses that should remain separate. Your data model should distinguish brand identity from legal entity identity whenever both matter.
For marketing catalogs and product feeds, a simplified brand name may be appropriate. Accounting, compliance, procurement, and contracting systems may need the full registered legal name instead. Instead of forcing every department to use one format, define fields for different purposes. A canonical brand field and separate legal entity field usually provide greater accuracy than aggressive text cleanup.
Standardize Spaces and Hyphenation
Extra spaces frequently enter databases through manual typing, imported spreadsheets, and copied text. Brand normalization should normally trim spaces at the beginning and end of values while replacing repeated internal spaces with a single space. These changes rarely affect brand meaning and can prevent unnecessary duplicates. They are among the safest normalization transformations to automate.
Hyphenation requires more judgment because a hyphen may be optional in some names but essential in others. For matching purposes, you might compare both “Blue-Star” and “Blue Star” using a secondary normalized key. The official display name should remain based on verified brand information. Removing every hyphen from every stored name can create visually incorrect results.
Word boundaries should also be reviewed before merging records. “Super Tech” and “SuperTech” could represent the same company, but they could also be different businesses. Automated normalization should therefore create potential matches rather than always assuming equivalence. Combining rules with confidence scoring or manual review reduces the risk of accidentally merging legitimate brands.
Handle Abbreviations and Acronyms
Abbreviations often create difficult brand matching situations. A company might be known publicly by initials while its supplier records contain the complete corporate name. Automatically assuming that an acronym and a long name refer to the same business can create false matches. Instead, validated alias mappings should connect known abbreviations to their canonical brand records.
Common corporate terms can sometimes be standardized safely within technical keys. Variations such as “Company” and “Co.” or “Corporation” and “Corp.” may be treated similarly when your business rules support it. However, these transformations should remain context-sensitive because shortened words can occasionally form part of an unrelated brand. Test rules against real data before applying them globally.
Acronym matching becomes more reliable when combined with additional attributes. Domain names, addresses, product identifiers, registration numbers, or supplier IDs can help verify whether two names represent the same organization. Brand normalization should not depend on text alone when richer signals are available. Multi-field matching significantly reduces accidental merges in large datasets.
Normalize Numbers and Special Symbols
Numbers can be core parts of brand identities and should not automatically be converted or removed. Brands such as “3M” demonstrate why numeric characters can carry essential meaning. A rule that strips numbers could turn a valid brand into an unusable value. Keep numeric characters unless your specific matching logic has a clearly tested reason to transform them.
Written numbers and numeric digits may occasionally appear as variations, such as “Seven Hills” and “7 Hills” These should not automatically be treated as equivalent without evidence because they could represent separate companies. If your data confirms they belong to the same brand, store one as an alias. Explicit mappings are safer than universal number-word conversion.
Symbols such as plus signs, ampersands, slashes, and mathematical characters require similar care. Some are decorative, while others are legally or commercially meaningful. Build normalization rules around observed variations within your dataset rather than assuming every symbol is noise. The safest framework preserves original values while creating a simplified comparison field for matching.
Manage Unicode and Special Characters
International brand data often includes accented letters, non-Latin scripts, special punctuation, and visually similar Unicode characters. Different systems may store the same visible text using different character representations. Unicode normalization can help standardize those technical differences before comparison. This is particularly important when data moves between international marketplaces, databases, and supplier systems.
Removing accents can sometimes improve search matching, but the original spelling should normally remain available. A customer searching without an accent may still need to find a brand whose official name includes one. Search systems can maintain accent-insensitive comparison keys while displaying the correct canonical version. That approach improves discoverability without changing the brand itself.
Transliteration should also remain separate from canonical naming. A Japanese, Arabic, Korean, or Cyrillic brand may have both a native-script name and an internationally used Latin spelling. Store verified variations as aliases rather than replacing one permanently with another. Multilingual brand databases work best when they support several valid representations linked to one stable entity.
Normalize Domains and Social Handles
Domain names frequently appear in brand datasets because people enter website addresses instead of company names. A value such as “example.com” may need to match the canonical brand “Example.” Normalization can remove protocols, “www,” paths, tracking parameters, and selected domain extensions when domains are being used specifically as identity signals rather than displayed names.
Social handles present similar challenges. A company may appear as “@exampleofficial” on one platform while its brand name is simply “Example.” Do not automatically treat handles as canonical names because usernames often include extra words or characters caused by availability limitations. Store social profiles in dedicated fields and use them as supporting evidence for entity matching.
Domains are especially valuable for deduplication because they can help distinguish similarly named companies. Two businesses may both use “Summit Consulting,” but their website domains can show that they are separate organizations. Combining normalized names with verified domains creates stronger matching than text alone. Domain information should therefore support identity resolution rather than replace the actual brand field.
Separate Parent Companies From Sub-Brands
A parent company and its brands should not automatically share one normalized name. Large organizations may own many brands that customers perceive as completely separate. Collapsing every subsidiary and brand into the corporate parent can damage product categorization, reporting, search filters, and customer experience. Your data model should support relationships without erasing individual identities.
Create separate records for each meaningful brand and connect them through ownership relationships when necessary. A sub-brand may have its own products, website, visual identity, and marketing strategy while still belonging to a larger organization. This structure allows analysts to report at both brand and parent-company levels. It also prevents normalization from becoming an uncontrolled merging process.
The same principle applies to product lines that resemble standalone brands. Determine whether customers, suppliers, and marketplaces consistently recognize the name as an independent brand before creating a separate entity. Establish documented criteria so teams make these decisions consistently. Brand architecture should be governed by business meaning, not only by textual similarity.
Apply Normalization to Product Feeds
Product feeds often receive brand names from multiple suppliers, creating inconsistent capitalization, punctuation, and spelling. One vendor may submit “Alpha Tech,” while another sends “ALPHA-TECH” and a third sends a legal company name. Normalization can map these variations to one canonical brand before products reach e-commerce filters, search pages, advertising systems, or marketplaces.
A centralized brand mapping table is useful when working with supplier feeds. Raw supplier values can remain stored for auditing while transformed values point to approved canonical brands. When a new variation appears, it can be reviewed and added to the mapping table. Future imports then resolve automatically without repeatedly correcting the same issue manually.
Avoid silently changing uncertain matches. If a supplier submits a brand value that could refer to several entities, route it to an exception queue instead of guessing. Wrong brand assignments can miscategorize products and damage merchant feeds. A good product data workflow automates obvious matches while preserving human review for genuinely ambiguous cases.
Use Brand Normalization in CRM Systems
CRM databases commonly contain duplicates because employees enter company names in different ways. “Greenfield Ltd,” “Greenfield,” and “GREENFIELD LIMITED” might become three accounts even though they refer to one customer. Normalized comparison keys help identify likely duplicates before sales activity, contacts, opportunities, and revenue become fragmented across several records.
Do not automatically merge CRM accounts solely because their normalized names match. Companies with common names may operate independently, and separate branches may require distinct records. Compare domains, addresses, phone numbers, tax identifiers, and account relationships before combining data. Matching should generate confidence, while business rules determine when records can safely be merged.
Once a verified master account exists, aliases can redirect future imports toward the correct record. This reduces duplicate creation and improves reporting accuracy. Sales teams can see a more complete customer history rather than searching through several variations. Good normalization therefore improves both data quality and the everyday usability of CRM systems.
Improve Search and SEO With Clean Brand Data
Consistent brand naming supports cleaner internal search experiences. If a shopping site stores several variations of the same brand, customers may see duplicate filters or incomplete search results. Mapping variations to one canonical brand ensures products appear together. Search engines inside the website can still recognize aliases so users find the correct products even when they type alternative spellings.
Brand normalization can also improve website structure. Consistent names make it easier to create stable category pages, metadata, breadcrumbs, structured information, and internal links. Constantly generating separate pages for minor spelling variations can create unnecessary duplication. A canonical brand record provides one dependable source for templates and content management systems.
SEO teams should still preserve the natural ways people search. If customers commonly use an abbreviation, old name, or alternate spelling, that variation may be useful within page copy or search functionality. Normalization should organize entities rather than erase language variation. Clean backend data and flexible frontend content can work together without creating duplicate brand records.
Build Reliable Entity Matching Rules
Entity matching determines whether two records refer to the same real-world brand. Begin with high-confidence transformations such as trimming spaces, standardizing case for comparison, and normalizing selected Unicode differences. Then apply carefully tested rules involving punctuation, legal suffixes, domains, and aliases. Each additional transformation should solve a known data problem rather than simply make strings look similar.
Use confidence levels instead of treating every possible match equally. Exact normalized names combined with matching domains may qualify for automatic linking, while names that only appear vaguely similar should require review. This approach creates a balance between automation and accuracy. High-volume systems become faster without allowing aggressive matching rules to create widespread data corruption.
Keep a record of why entities were matched. Audit information might show whether the decision came from an exact alias, domain match, manual approval, or automated rule. Explainable matching makes errors easier to investigate and reverse. It also helps data teams evaluate which normalization rules are producing useful results and which ones need refinement.
Create a Brand Alias Dictionary
An alias dictionary stores known variations that should resolve to a canonical brand. Variations may include abbreviations, former names, legal names, common misspellings, supplier-specific labels, and localized versions. Instead of repeatedly applying uncertain fuzzy matching, the system can use approved aliases. Over time, the dictionary becomes an increasingly valuable part of your master brand data.
Every alias should point to a stable brand identifier rather than simply another text value. This prevents chains where one alias points to another alias and eventually becomes difficult to manage. A direct relationship between alias and entity makes updates easier. If the canonical display name changes later, existing aliases can continue resolving correctly without rebuilding every mapping.
Control who can add or modify aliases. An incorrect alias can cause large numbers of records to merge into the wrong brand during automated imports. Review new aliases using supporting evidence and keep a history of important changes. Governance may seem unnecessary for small datasets, but it becomes critical once normalization affects thousands or millions of records.
Handle Fuzzy Matching With Caution
Fuzzy matching can identify similar names that simple rules miss. Typographical errors such as “Microsof” instead of “Microsoft” may be obvious to a human but difficult for exact matching systems. Similarity algorithms can flag these records for review. They are especially useful when datasets contain manually entered names with inconsistent spelling.
However, similarity does not prove identity. Two legitimate brands can have names differing by only one letter, particularly in large international datasets. Automatically merging them because a similarity score is high can create serious data-quality problems. Fuzzy matching should usually act as a candidate-generation tool rather than an unquestioned decision-making system.
Improve fuzzy matching by adding context. Compare domains, locations, product categories, identifiers, and existing relationships alongside name similarity. A moderately similar name with the same domain may be a stronger match than two nearly identical names from unrelated countries. Context-aware entity resolution produces more reliable results than applying one universal string similarity threshold.
Manage Multilingual and International Brand Names
Global databases need rules for brands that operate under different names across countries or languages. A company may use one official global brand while maintaining localized spellings, transliterations, or commercial names in particular regions. Do not force every localized form into a single visible string. Instead, connect regional variants to the same entity while retaining appropriate display values.
Country-specific legal suffixes should also be handled carefully. Removing terms such as GmbH, SARL, BV, Pty Ltd, or similar corporate designations may improve commercial brand matching, but those terms can remain important for legal records. Maintain clear distinctions between commercial brands, registered organizations, and local operating entities when your systems require all three.
Language information can make normalization safer. Store script, locale, country, and transliteration fields where relevant instead of guessing from characters alone. This allows websites and applications to display the right brand representation for each audience. International normalization works best when it expands the data model rather than aggressively simplifying every name into English characters.
Establish Brand Data Governance
Normalization rules should be documented so teams know exactly how brand names are handled. Define which transformations are automatic, which require review, and which fields preserve original values. Include examples covering capitalization, punctuation, legal suffixes, spacing, aliases, Unicode, and domains. Written standards prevent different departments from creating conflicting rules inside their own systems.
Assign ownership for brand master data. A data operations, catalog, merchandising, or governance team should be responsible for approving canonical records and resolving uncertain matches. Without ownership, duplicate brands can reappear because nobody knows who should make final decisions. Clear responsibilities make normalization sustainable instead of turning it into a one-time cleanup project.
Track data-quality metrics such as duplicate rates, unresolved aliases, manual review volume, and failed mappings. These measurements help identify where rules need improvement. If one supplier repeatedly generates unmatched brand names, the problem may require a supplier-specific mapping process. Governance becomes more effective when teams measure recurring issues rather than only correcting individual records.
Build a Repeatable Normalization Workflow
A practical workflow begins by preserving the raw brand name exactly as received. Never overwrite source data before validation because original values are useful for audits and troubleshooting. Next, create a normalized comparison key using safe transformations such as trimming spaces and case folding. More aggressive rules can then be applied in separate stages.
Compare the normalized value against canonical names and approved aliases. High-confidence matches can be linked automatically, while uncertain candidates move into a manual review queue. New confirmed variations should be added to the alias dictionary so future records resolve more efficiently. This creates a learning system where human decisions gradually improve automation.
Finally, publish the approved canonical brand to downstream systems while retaining the original input and matching history. Product feeds, websites, CRMs, analytics tools, and reporting platforms can then rely on the same master identity. A repeatable pipeline prevents teams from performing independent cleanup and creates consistent brand data across the organization.
Avoid Common Brand Normalization Mistakes
One common mistake is using a single transformed string for both matching and display. Converting everything to lowercase, removing punctuation, and deleting suffixes may create useful comparison keys, but the result often looks inappropriate to customers. Preserve an approved canonical display name separately. Technical normalization should support brand identity rather than replace it.
Another mistake is assuming similar names always represent the same company. “North Star,” “NorthStar,” and “North-Star” may belong together, but similarity alone is not enough evidence. Verify uncertain records using domains, identifiers, locations, or human review. Aggressive automatic merging can be more damaging than keeping a small number of duplicates temporarily.
Teams also make mistakes when they create normalization rules without testing real datasets. A transformation that fixes hundreds of duplicates may unexpectedly merge unrelated brands. Run proposed rules against representative samples and review the resulting matches before deployment. Data normalization should be treated like software logic: tested, monitored, documented, and revised when edge cases appear.
Conclusion
Brand name normalization rules create a reliable foundation for product catalogs, CRM systems, analytics, search, marketplaces, and master data management. The objective is not to make every brand look identical. Instead, normalization should recognize different representations of the same entity while preserving each brand’s correct public identity and meaningful business relationships.
The strongest approach separates raw input, normalized matching keys, aliases, and canonical display names. Safe rules can automate capitalization differences, spacing, selected punctuation, and known variations, while uncertain cases remain available for review. Stable brand identifiers make the system even more reliable because relationships do not depend entirely on text values that may change.
Treat normalization as an ongoing data-quality process rather than a one-time cleanup. Document standards, maintain an alias dictionary, monitor duplicate records, and test new transformations before applying them widely. When brand data is governed carefully, organizations gain cleaner reporting, stronger search experiences, easier integrations, and more dependable information across every connected platform.
What is a normalized brand name?
A normalized brand name is a standardized representation used to match different versions of the same brand. It may remove formatting differences while remaining linked to the correct official display name.
Should brand names always be converted to lowercase?
No. Lowercase values are useful for case-insensitive matching, but customer-facing names should preserve official capitalization. Keep a separate normalized comparison key instead of changing the canonical display name.
Should LLC and Inc. be removed from brand names?
They can sometimes be removed from comparison keys when matching commercial brands. However, legal suffixes should remain when identifying registered entities or when removing them could incorrectly merge separate businesses.
How should special characters in brand names be handled?
Preserve meaningful characters in the official brand name while simplifying selected characters only within matching keys. Symbols such as ampersands, hyphens, and apostrophes should not be removed blindly.
What is the best way to prevent duplicate brand records?
Use canonical brand IDs, normalized comparison keys, verified aliases, domain matching, and manual review for uncertain cases. This combination is safer than relying solely on exact names or aggressive fuzzy matching.